Few-shot learning enables language models to tackle tasks with a handful of examples, rather than through task-specific training on large datasets. But high few-shot performance also depends not on the task itself or the underlying aptitude, but on the reliability with which the model understands the predicted outputs and assigns ranks. And calibration before use makes the predicted outputs consistent even for novel tasks and fewer examples.
This topic connects closely with the broader field of machine learning, where model accuracy, uncertainty, generalization, and reliable predictions are essential.
This Article Belongs to Machine Learning
Table of Contents
What is Calibration in Language Models?
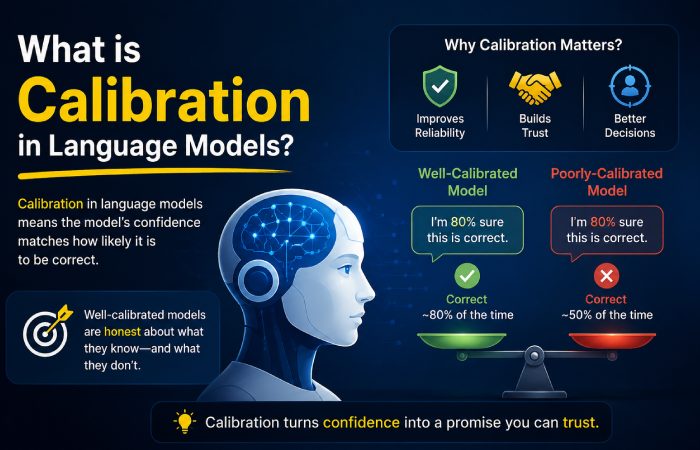
Calibration refers to an aspect of a model whereby the confidence assigned to a prediction is aligned with how accurate the prediction actually is likely to be. If a model makes a set of predictions with confidence 80%, the calibrated system would make correct predictions 80% of the time.
Calibration is particularly handy in few-shot learning where we don’t train with many examples: even slight variations in word choices, distribution of labels and examples can easily affect the outcome of the model.
Why is Calibration Important for Few-Shot Learning?
Few-shot prompting can be impressive, but it sometimes leads to poor performance when the model is confidently but incorrectly performing on.
| Benefit | How It Helps |
| Improved reliability | Reduces excessively confident predictions |
| Better confidence estimates | Helps users understand how certain a prediction is |
| Improved generalization | Supports more consistent performance on unfamiliar examples |
| Reduced prediction bias | Can compensate for systematic preferences in model outputs |
| Better decision-making | Makes probabilistic outputs more useful in practical applications |
The ability to use calibration effectively proves its worth in situations such as influencing business decisions, research findings, or the automate control systems in real-time processes where an incorrect forecast will be detrimental.
How Does Calibration Improve Few-Shot Performance?
A language model may know a lot but it might just express some answers at inappropriate probabilities, for instance, with a few demonstration examples for classification a language model might prefer a particular label due to the wording and how many times a certain label occurred compared to the label being truly relevant for the input.
Calibration methods attempt to correct this behaviour. Instead of simply selecting the model’s highest-confidence answer, the system adjusts its output probabilities so they better represent expected performance.
One influential approach is contextual calibration, introduced in research on improving few-shot learning with pretrained language models. The method examines the model’s behavior under a neutral or content-free input and uses that information to reduce unwanted biases in the predictions.
Common Calibration Techniques
Different calibration approaches can be used depending on the model and application.
| Technique | Description | Typical Use |
| Temperature Scaling | Adjusts the sharpness of predicted probabilities using a temperature parameter | Classification and probability calibration |
| Platt Scaling | Learns a mapping between model scores and calibrated probabilities | Binary classification |
| Ensemble Methods | Combines predictions from multiple models or runs | Improving robustness |
| Contextual Calibration | Uses model responses to neutral inputs to correct contextual or label biases | Few-shot prompting |
Difference Between Probability Calibration and Contextual Calibration
Probability calibration and contextual calibration address related but different problems. Probability calibration aims to make predicted confidence scores reflect the actual frequency of correct predictions. For example, among predictions assigned 80% confidence, approximately 80% should be correct over a sufficiently large evaluation set.
Contextual calibration focuses more specifically on biases introduced by few-shot prompts. A language model may prefer certain labels because of their wording or the structure of the examples. By examining predictions for a content-free input, contextual calibration estimates these preferences and adjusts the output scores. This can improve few-shot classification without requiring extensive task-specific training.
1. Temperature Scaling
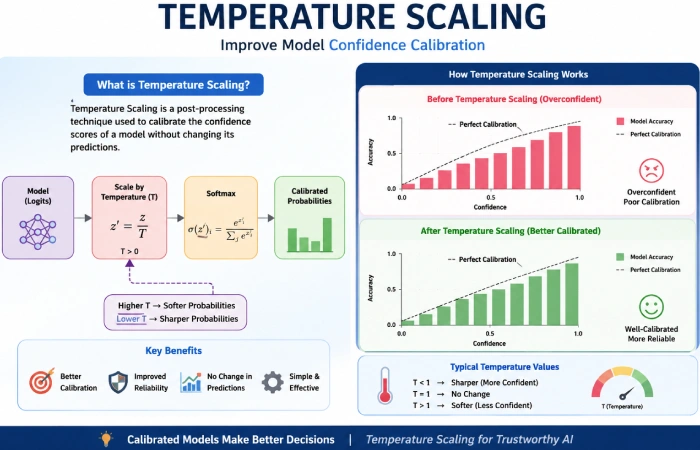
Temperature scaling modifies the model’s logits before converting them into probabilities. A higher temperature generally produces a softer probability distribution, while a lower temperature makes predictions more concentrated.
The temperature is typically selected using validation data. This approach is relatively simple because it does not require changing the underlying language model.
2. Platt Scaling
Platt scaling trains a separate calibration function to transform a model’s raw scores into probabilities. It is widely associated with classification systems and can be useful when sufficient held-out data is available for calibration.
3. Ensemble Methods
Another technique is to average the predictions of multiple models, prompts, or sampling runs. It’s possible to smooth over some biases with model averaged predictions and stabilize confidence estimates to some extent.
4. Contextual Calibration
This technique-contextual calibration-is especially useful for few-shot language-model applications. Unlike typical approaches that expect the model’s initial output probabilities to be objective, it measures the model’s reactions to a completely neutral -or “content-free”-input and corrects its responses.
That could help compensate for unintended biases introduced by the wording of a prompt, the selection of the labels used in a task, or the quality of the example provided.
How is Calibration Evaluated?
Calibration should be evaluated separately from simple accuracy. A model can achieve good accuracy while still being poorly calibrated.
Common evaluation methods include:
| Metric | What It Measures |
| Reliability Diagram | Compares predicted confidence with observed accuracy |
| Expected Calibration Error (ECE) | Measures the difference between confidence and actual accuracy across probability groups |
| Brier Score | Evaluates the quality of probabilistic predictions |
| Accuracy | Measures how often the model makes correct predictions |
A reliability diagram is particularly useful because it provides a visual representation of whether a model is overconfident or underconfident.
Best Practices for Calibrating Few-Shot Models
Calibration functions as part of the evaluation process rather than a final correction. Developers should: test prompts on a balanced set of inputs, remove calibration inputs from evaluation inputs and examine a comparison of calibration/non-calibration tests.
Another thing to keep in mind is that calibration doesn’t necessarily improve every aspect of a language model. A calibrated language model could end up being more confident in its predictions without necessarily boosting their raw accuracy-the aim is to ensure confident predictions are worthy of that confidence.
Practical Steps for Calibrating a Few-Shot Language Model
A practical calibration process begins by preparing a representative dataset containing examples that reflect the intended application. First, evaluate the model using a fixed prompt and record its predictions and confidence scores where available. Next, select an appropriate calibration method, such as temperature scaling or contextual calibration, depending on the model’s outputs and task requirements.
Use separate data for fitting calibration parameters and evaluating the final results. Compare calibrated and uncalibrated predictions using reliability diagrams, Expected Calibration Error, and the Brier score. Finally, test the system on unfamiliar examples and monitor its performance when prompts or data distributions change. This helps determine whether calibration remains useful in practice.
Conclusion
Check the Predictions Before Application. Many have recently explored reducing overconfidence, accounting for bias and overall building models that you can trust. Calibrate Before Use: Improving Few-Shot Performance of Language Models shows us why this needs to be part of successful machine learning development. You can also explore different career paths in machine learning to understand how these skills are applied across different professional roles. Even though models make predictions that seem correct most of the time they won’t if you have few shots of data for your model to rely on.
Methods like temperature scaling, Platt scaling, assembling, and contextual calibration bring varied improvements to prediction quality. Developers can improve their few-shot systems by considering both accuracy and calibration to make their systems effective and trustworthy.